Claude Opus 5 Launches With 1M Context at Half the Price of Fable 5
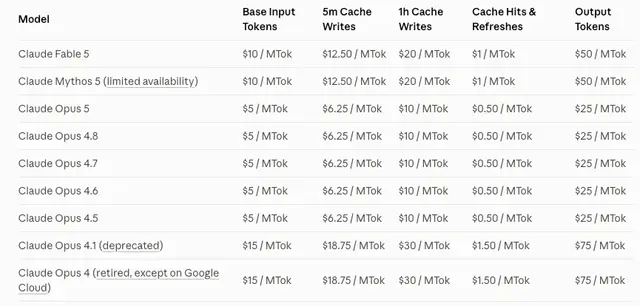
Anthropic has released Claude Opus 5 for complex agentic coding and enterprise work, with 1M context, 128K output, and API pricing at half the cost of Claude Fable 5 today.
12 articles
Browse 12 articles, tool introductions and practical notes about AI models, ordered by publication date.
Anthropic has released Claude Opus 5 for complex agentic coding and enterprise work, with 1M context, 128K output, and API pricing at half the cost of Claude Fable 5 today.
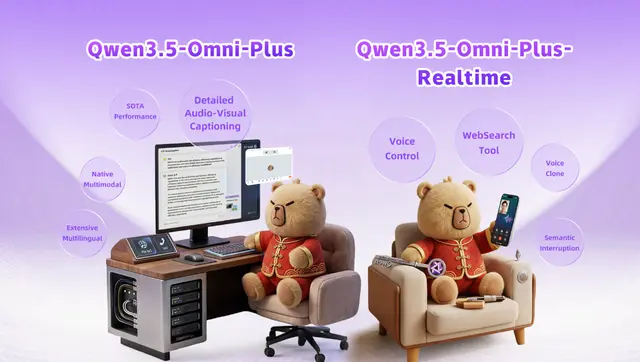
Qwen3.5-Omni: Native multimodal model with 256k context, 10-hour audio, 4M frame video support. Thinker-Talker + Hybrid-Attention MoE architecture achieves SOTA in 215 benchmarks.
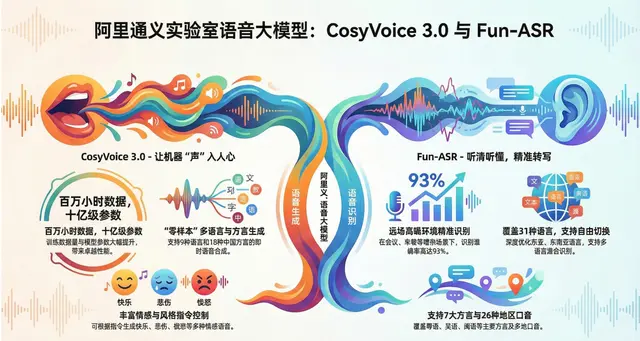
Released on 2025-12-15, CosyVoice 3.0 features 9 languages, 18+ dialects, and pronunciation inpainting. This guide covers model setup, inference, and full local deployment.
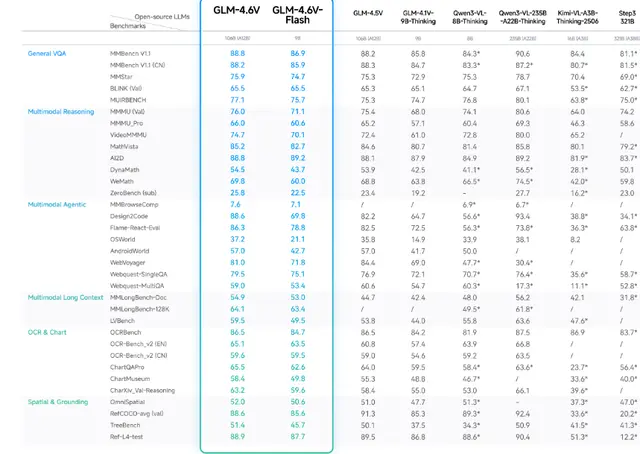
GLM-4.6V free open-source multimodal AI model guide. 106B/9B versions, 128K context, image recognition, OCR, PDF understanding, video analysis.
Qwen3-Omni-modal model for text, image, audio and video with real-time speech. Thinker–Talker + MoE, multi-codebook for low latency; 119 languages; vLLM/Transformers tips.
Introducing Alibaba Cloud's Qwen3 LLM series (0.6B-235B), featuring MoE and Dense architectures for optimal performance and efficiency. Supports 119 languages with advanced coding and math capabilities.
Introducing Google's Gemma 3 QAT: A breakthrough in quantization-aware training that enables edge AI deployment with FP16-level performance at quarter memory usage.
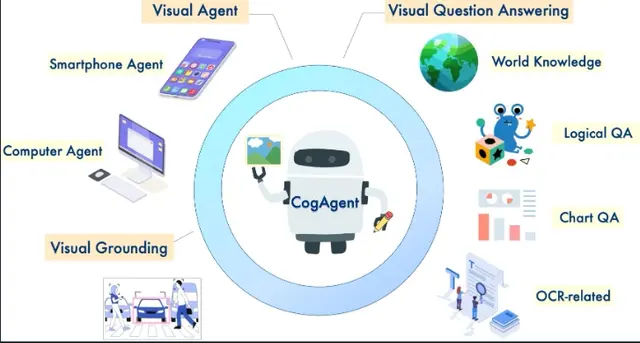
CogAgent-9B: A 9B-parameter GUI agent by Zhipu AI and Tsinghua University that excels in interface understanding and automation, outperforming other models in MM-Vet and more benchmarks
In-depth comparison and analysis of popular AI model deployment tools including SGLang, Ollama, VLLM, and LLaMA.cpp, helping developers and users choose the most suitable AI model deployment tool
"Deep dive into DeepSeek-V3 model. Its architecture combines MLA and DeepSeekMoE with innovative load balancing. Trained on 14.8T tokens, powered by HAI-LLM framework and FP8 technology. Enhanced by innovations like MTP, performance surpasses open-source and approaches closed-source models. Cost-effective with low training and API costs, a key reference in AI advancing language models."
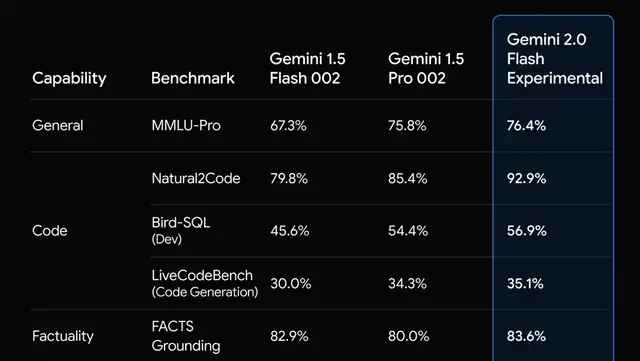
Discover Google Gemini 2.0 Flash: 2x faster performance, enhanced multimodal capabilities, and breakthrough AI features. Learn how this next-gen AI model transforms development and analysis.
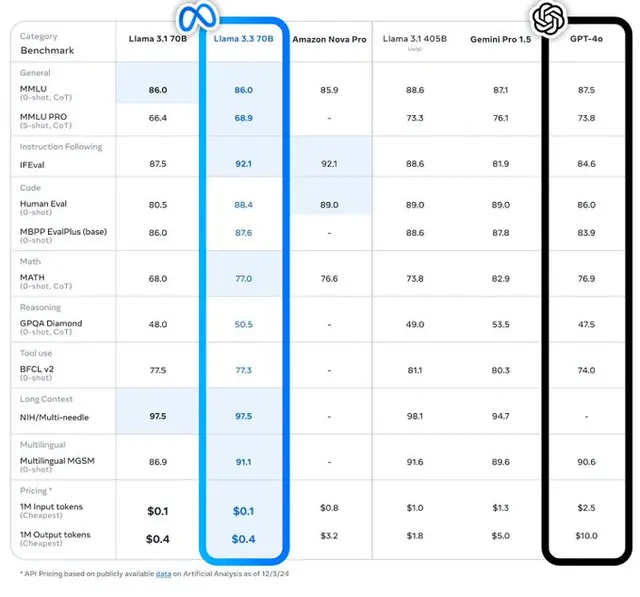
Meta releases Llama 3.3: 70B parameter model matches 405B performance, with 128K context window and 8-language support. A breakthrough in open-source AI.