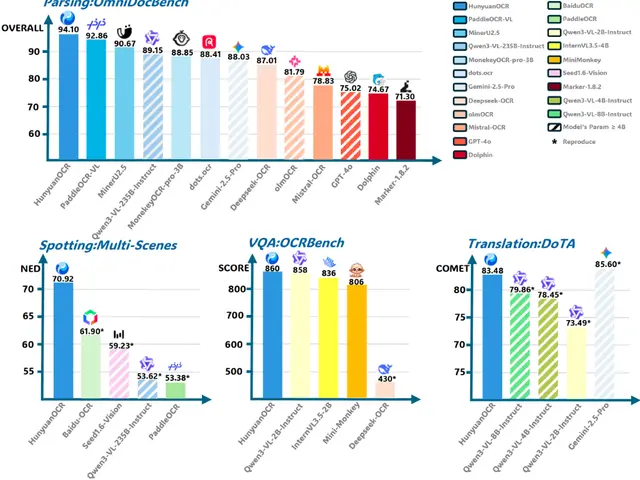
HunyuanOCR Tutorial: 1B Param Model Outperforms DeepSeek/PaddleOCR/Qwen | Deployment Guide
HunyuanOCR: Tencent 1B OCR model beats DeepSeek-OCR (92% vs 10% on cards). Supports 100+ languages, vLLM OpenAI API deployment. Full code examples included.
5 articles
Compare vision-language models for image understanding, documents, interfaces and video-related tasks.
Evaluate vision-language models with the image types and tasks you need, such as document questions, interface grounding or scene understanding. Test resolution, small text and multiple images rather than relying on a single simple example.
HunyuanOCR: Tencent 1B OCR model beats DeepSeek-OCR (92% vs 10% on cards). Supports 100+ languages, vLLM OpenAI API deployment. Full code examples included.
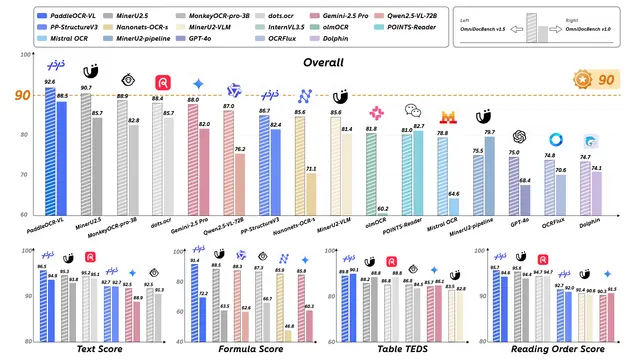
PaddleOCR-VL Tutorial: Baidu 0.9B AI model for 109-language OCR. Parse text, tables, formulas & charts with Docker/Python API. SOTA performance beats GPT-4V.
IBM Research's SmolDocling, a 256M-parameter vision-language model, delivers fast document OCR and multimodal processing at 0.35s per page on consumer GPUs, handling text, formulas, code and charts efficiently.
A comprehensive guide to InternLM-XComposer-2.5-OmniLive multimodal model: Supporting image, video and audio processing with complete deployment tutorials and performance evaluation.
Ivy-VL: 3B lightweight vision-language model outperforms 7B models, enables real-time AI glasses, ranks #1 on OpenCompass under 4B. Open-source edge AI solution by AI Safeguard, CMU & Stanford.